Victor Barres
Research Scientist at Mercor.

I build and study conversational AI agents — systems that have to get real work done while sustaining long, coherent interactions with the people they work with. Doing both at once is where most of what’s hard about deploying them lives.
I’m a founding member of the APEX research team at Mercor, where I’m taking that beyond the single conversation: agents inside real organizations, working with people, and transforming the work itself — and how we measure that well enough to understand it, and help shape it. With Aden Barton, Nicolai Foss and Henrik Nielsen, I’m building a bridge between organization theory and AI evaluation (Harder Than the Task). Before that, I led the τ-Bench family of agent benchmarks at Sierra (live leaderboard at taubench.com).
My background is in computational cognitive science and cognitive linguistics, and I’ve spent years building real-world conversational systems across several startups. More on how I think about the work →
the τ-Bench family
At Sierra I led the τ-Bench family of agent benchmarks (originally introduced there in 2024) — code, repo, public leaderboard, and a sequence of extensions, a line I still contribute to:
- τ²-Bench — extends τ-Bench to a dual-control setting where both the agent and the user can act on the world.
- τ-Knowledge — knowledge-retrieval domain.
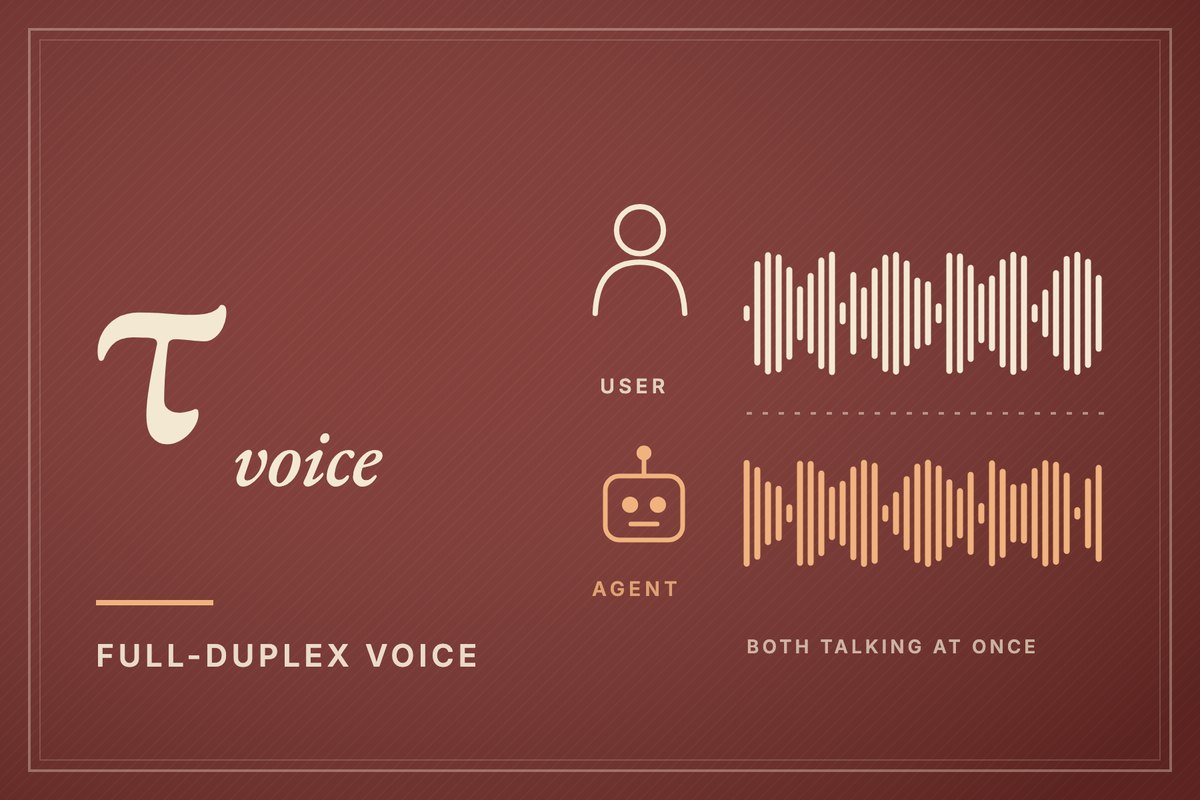
- τ-Voice — first benchmark to measure full-duplex voice agents on realistic, grounded customer-service tasks.
- τ³-Bench — combines τ-Knowledge and τ-Voice with community-contributed task fixes and code improvements.
- τ-i18n — extends voice-agent evaluation across languages: Spanish, Brazilian Portuguese, Hindi, Korean and Mandarin.
- τ-Entity — can voice agents get the details right? Someone’s name, phone number or email, over the phone.
- Hyper-τ-Bench — flips τ-Bench around: the agent has to build the agent, from scattered requirements and a client who holds the rest, and we grade what it ships.
User simulation runs through all of it — to build and evaluate agents that talk with people, you need simulated people you can trust. I’m co-organizing the NeurIPS 2026 workshop on Grounded User Simulation for Model Evaluation and Training (Paris, December 12).
news
| Nov 05, 2026 | New paper with Aden Barton, and with Nicolai J. Foss and Henrik M. Nielsen of Copenhagen Business School, building a bridge between organization theory and AI evaluation: Harder Than the Task (blog). Benchmarks are made of tasks, but a job is done with others, who hold information, make decisions and depend on you. Only 16% of benchmarks measure any organizational dimension, though attention is growing fast: from 14% claiming one in 2023 to 33% in 2026. |
|---|---|
| Oct 22, 2026 | Talk at Training Agents IRL (GitHub, San Francisco; hosted by Hugging Face / OpenEnv): Fit for Purpose: Environments, benchmarks, and the metrology of AI agents (slides, video). Attach a task and a grader, and an environment produces a number. You can judge it by what it does to the model, or by what it tells you about the model: a reward is not a measurement. |
| Oct 21, 2026 | Two new voice-agent benchmarks with Soham Ray and the Sierra team, with leaderboards on taubench.com. τ-Entity starts from something that sounds trivial: getting someone’s name, phone number or email right over the phone. When agents do check a wrong value, only 24–37% get repaired. τ-i18n takes the τ-bench airline, retail and telecom tasks into Spanish, Brazilian Portuguese, Hindi, Korean and Mandarin, and scores task completion, interaction and generation separately. They don’t line up. |
| Sep 04, 2026 | Hyper-τ-Bench released — do agents have what it takes to build agents? The best developer agent ships 23.9%; an engineer’s hand-built reference reaches 82.2%. Open source, with a leaderboard that takes submissions by pull request. |
| Jul 13, 2026 | Co-organizing the NeurIPS 2026 workshop on Grounded User Simulation for Model Evaluation and Training — Paris, December 12. |
selected publications
- NAACL
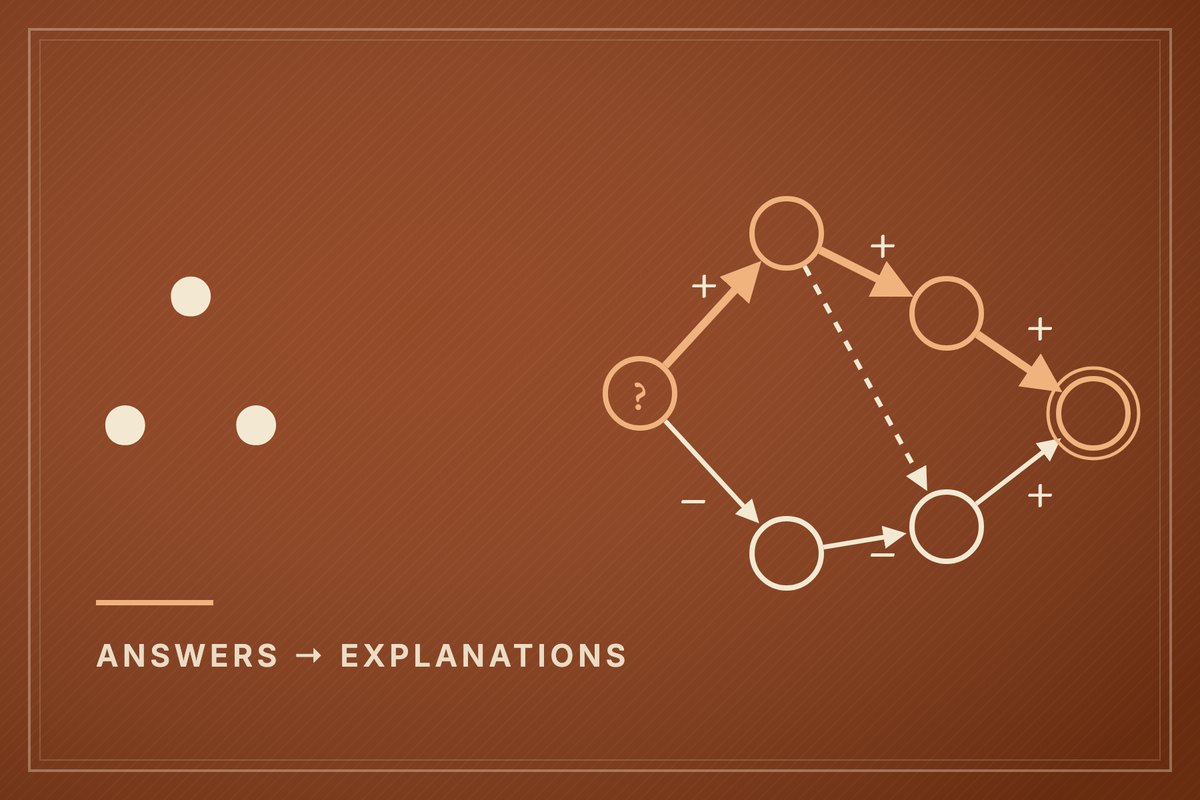 From Generating Answers to Building Explanations: Integrating Multi-Round RAG and Causal Modeling for Scientific QAIn Proceedings of the 2025 Conference of the Nations of the Americas Chapter of the Association for Computational Linguistics: Human Language Technologies (Industry Track), 2025